Used well, generative AI can make the person using it measurably better. But it also makes what they produce resemble what everyone else is producing. Both effects have now been measured, and most companies are tracking only the first.
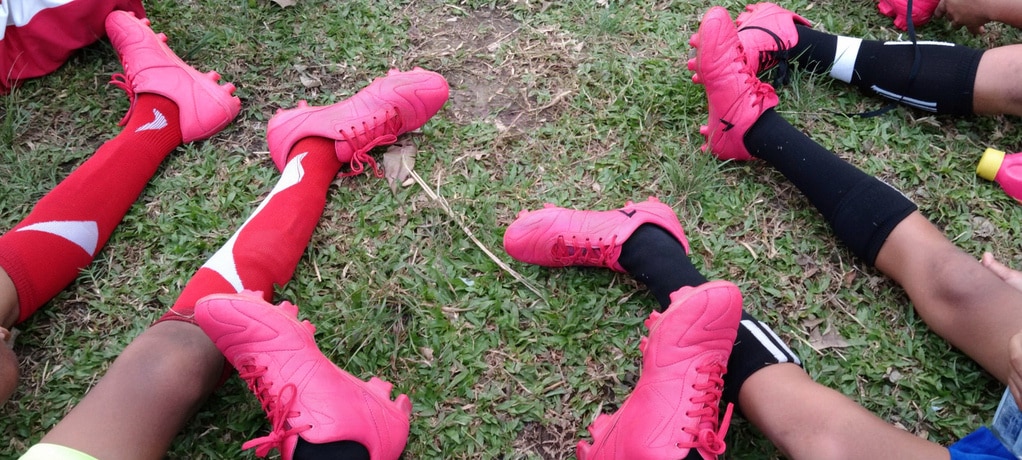
At the World Cup this summer, an unusual number of players took the field in pink boots. Not one brand’s pink: Nike, Adidas, Puma, New Balance, and Skechers each arrived at pink-centric footwear for the tournament independently, on development cycles running 18-months to two years.
The very reasonable explanation the brands have offered is that pink sits opposite green on the color wheel, which makes it the most visible color against a pitch. Testing showed maximum impact on television and mobile screens, and no participating nation wears pink kits, so there was no risk of clashing.
But journalist Jacob Ward offered a second explanation: the brands consulted the same trend-forecasting source and got the same answer.
Both of these accounts can be true. Five sophisticated competitors, each optimizing correctly against the same objective, using substantially the same inputs, arrived at the same output. Nobody made a mistake. But that’s precisely what makes this scenario worth paying attention to—convergence was the correct result of each company’s individual process. The same logic runs inside a company. Departments have best practices, but they also have their own cultures and habits, and those idiosyncrasies are often where the advantage actually lives. Align every one of them to the statistical mean and you may be flattening the thing that made you difficult to copy.
The trade-off is now measurable
The convergence effect is no longer a matter of inference. It has been demonstrated experimentally.
In a study published in Science Advances in July 2024, Anil Doshi and Oliver Hauser asked 300 writers to produce short stories, with varying levels of access to AI-generated story ideas, and had 600 evaluators assess the results. Writers with AI assistance produced measurably better work: roughly 8% higher on novelty and 9% on usefulness, with the largest gains going to the least naturally creative writers, whose scores rose by around 11%.
The stories also became about 11% more similar to one another.
That’s the trade in one sentence. Every individual writer was better off. But the collection they produced was less varied. And the writers who gained the most—the ones for whom the tool was most valuable—were the ones contributing most to the homogenization. It’s worth being precise about what converged. The writers did not adopt a common method — each worked with the tool in their own way, and anyone watching them would have seen more variation, not less. What converged was the output. That distinction matters inside a company, because the visible signal points the wrong way: teams feel more individual even as the work they ship grows more alike.
It’s not difficult to see the corporate analog. The function under the most pressure to adopt AI is usually the one with the thinnest bench, where the gains are largest and most visible. That function will improve. It will also start producing work that looks a great deal like what the same function at three competitors is producing, for the same reason and at the same time.
Why the individually correct choice is collectively bad
Jon Kleinberg and Manish Raghavan captured this in the Proceedings of the National Academy of Sciences in 2021, in work they call algorithmic monoculture. Their result is that when many decision-makers converge on the same algorithm, overall decision quality can decline—even when that algorithm is more accurate than the alternatives for any single decision-maker considered in isolation.
The mechanism is correlated error. Independent judgments, each imperfect, produce a distribution; the mistakes are uncorrelated, and some decisions land well. Identical judgments, each individually superior, produce identical outcomes — including identical blind spots, arriving everywhere at once.
For an executive, the practical implication is uncomfortable, because it means the usual test fails. “Is this tool better than what we were doing?” is the wrong question, or at least a badly incomplete one. The tool can be better for you and worse for your position at the same time, and nothing in your own results will reveal it. The evidence only appears when you look at what your competitors shipped.
What is left to be defensible about.
If capability is converging, the question becomes what does not.
Seema Amble of Andreessen Horowitz made a version of this argument in September, writing about vertical software companies facing both incumbents and general-purpose AI agents. Her conclusion: the durable position is not owning the system of record but being the best at performing the entire job — “the job is bigger than the record.” Contracts are not legal matters; tickets are not resolutions. Work crosses applications, teams, and companies, and a company that sees the whole of it sees things that no one operating inside a single record can.
What she is describing is a learning loop. The vertical company observes the corrections, the rejected alternatives, the reasoning behind expert judgment calls — none of which is in anyone’s training data, and all of which compounds. The traits she identifies in defensible markets follow from this: work that requires expert judgment, happens frequently, produces measurable results, and can be improved iteratively.
This also explains something about the current capital environment that otherwise looks strange. Spending used to buy market share, and market share was the moat. That trade has stopped clearing, and the money is turning inward — toward positions that cannot be bought into existence, only grown.
Three questions for any AI initiative
Could a competitor buy — or build —this outcome next quarter? If the capability is fundamentally a procurement or build decision, it’s a cost floor rather than an advantage. Worth doing, frequently urgent, and not a moat. The mistake is not in funding it; it’s in making it your differentiator.
Then ask the harder version of the same question. Can your customers now build what you used to deliver? The cost of building has fallen for them too, and the capabilities most at risk are the ones you have historically charged for because they were difficult — not because they were valuable. Where those two things were the same, you are fine. Where they weren’t, the gap is closing from a direction most competitive analysis doesn’t look.
Does it compound? Does running this process generate proprietary signal — corrections, exceptions, expert judgment, outcome data — that makes the next run better and is available only to you? Or does it produce the same output faster, permanently? The first builds a position. The second buys time.
Does it narrow the company or widen it? Focus requires deciding what you are not, and AI is exceptionally good at making it cheap to be more things. An initiative that expands what you can plausibly do is usually the one making you easier to copy, because everyone else’s tools are expanding in the same direction at the same rate.
There is a fourth question worth asking of the inputs themselves. If a competitor asked the same model the same question, how different would the answer be? The differences that matter will come from what you feed it that no one else has — your own customer data, your own outcomes, your own accumulated judgment. Companies without that are not building strategy. They are querying a shared oracle and receiving, as everyone else is, the shared answer.
Being right is not the same as being different
None of the brands did anything wrong in sending their team out in pink cleats. Five competitors ran capable processes and reached defensible conclusions. The story is instructive because the outcome wasn’t a product of carelessness. Each company asked whether it had the right answer, and each one did.
The question that would have caught it is a different one. Not is this correct? but what is everyone else likely to conclude, and do we want to be standing there? Nothing in a company’s own results would raise that kind of question, because internally the work looks like progress, and the evidence only exists in what competitors ship. Looking there deliberately, and treating similarity as a finding rather than a coincidence, is the cheapest source of differentiation most companies currently have.


